In the modern enterprise, the "cloud" has become the de facto digital warehouse. We have successfully offloaded the burden of physical storage to hyperscalers, theoretically granting us access to petabytes of information at the click of a button. Yet, for all our progress, a persistent friction remains: the "download bottleneck." Whether you are a video editor waiting for a 500GB project to sync or an AI agent parsing through thousands of fragmented datasets, the time spent moving data from the cloud to the local machine remains a significant operational tax.
However, a startup simply named Space is looking to dissolve that friction. Having recently secured $2.4 million in a pre-seed funding round, the company is moving beyond the standard corporate buzzwords of "synergy" and "paradigm-shifting" to offer a tangible solution: a file system that makes cloud-based storage behave exactly like a local solid-state drive (SSD).
The Core Innovation: Moving Beyond Syncing
For decades, our approach to cloud storage has relied on synchronization. Tools like Dropbox, Google Drive, and OneDrive function by ensuring that a copy of a file exists on both the server and the local device. While this provides peace of mind and offline accessibility, it is fundamentally inefficient. When dealing with "digital monstrosities"—4K video files, complex CAD models, or massive machine-learning training sets—waiting for an entire file to transfer just to edit a single frame or byte is archaic.
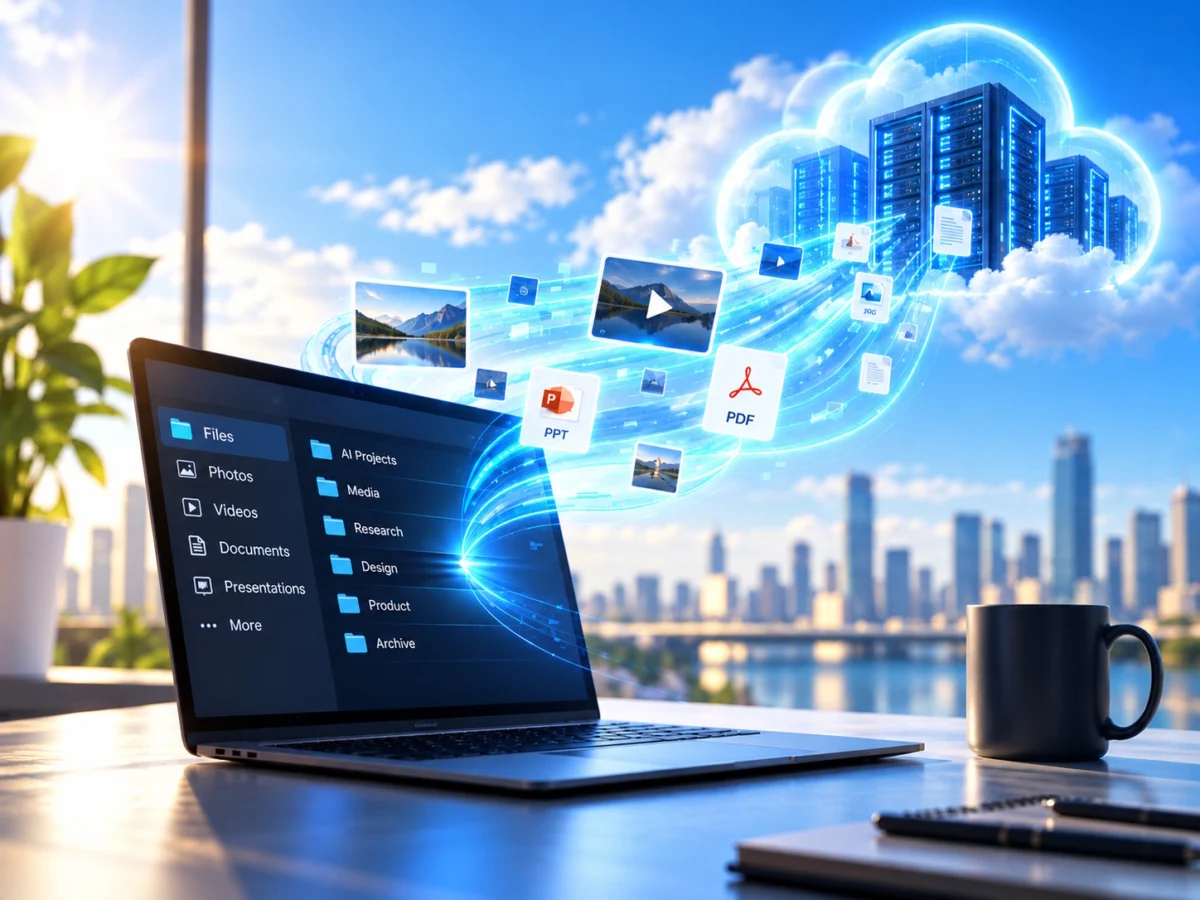
Space proposes a different architecture. By operating at the filesystem level, the Space app allows users to mount a "virtual drive." To the computer—and, more importantly, to the applications running on it—this drive appears as a local volume. When a user or an AI agent opens a file, Space does not download the entire payload. Instead, it streams the specific byte ranges required in real-time.
"The cloud solved storage," says Jason Zhao, co-founder of Space. "AI makes access the new bottleneck."
Chronology of a Breakthrough
The genesis of Space traces back to the frustrations of its founding team during their tenure at a previous venture, Eden. Operating as a lean, 10-person team, they were tasked with an aggressive content strategy that necessitated the movement of terabytes of media files on a weekly basis.
The team initially fell into the trap of assuming the problem was one of "discoverability." They invested heavily in building sophisticated search tools to help them find their files faster. While this solved the indexing issue, it highlighted a more profound problem: once a file was found, the team still sat idle while waiting for the data to migrate from the cloud to their workstations.
- Late 2025: The first functional prototype of the Space File System (Space FS) was developed. The core objective was to prove that a file could be utilized by a standard application (like Adobe Premiere or Blender) without the prerequisite of a full local download.
- The Validation Phase: Once the streaming technology was proven viable, the team spent months refining the protocols to ensure low-latency performance across various media types, including PDFs, high-bitrate video, and heavy datasets.
- Present Day: Following their $2.4 million pre-seed round, the company is transitioning from a proof-of-concept to a scalable enterprise solution, targeting both individual power users and large-scale corporate entities.
Supporting Data and Technical Architecture
During a live demonstration, the performance metrics of Space FS were striking. When scrubbing through high-resolution video files, the time-to-first-frame was essentially instantaneous—often appearing faster than accessing similar files from a physical, locally installed hard drive.
Technical benchmarks provided by the company indicate that the latency overhead for accessing cloud-resident data via Space is a mere 18 to 20 milliseconds slower than local storage. This creates a near-transparent user experience where the distinction between "local" and "cloud" effectively vanishes.
The system currently operates through two primary delivery models:

1. Space FS (The Native Approach)
For individuals and small teams, the preferred method is to migrate data into the Space File System. In this environment, Space "mutates" the data, using proprietary sharding techniques to optimize for high-speed, on-demand streaming. This provides the highest performance tier and is ideal for creative professionals and developers.
2. Space Enterprise (The "Bolt-On" Approach)
Recognizing that large Fortune 500 companies cannot simply "migrate" petabytes of legacy data into a new system, Space offers an enterprise integration layer. This infrastructure sits on top of existing object storage. While it does not utilize the full performance benefits of the native Space FS, it provides a streaming layer that dramatically improves access times without requiring a massive data migration project.
Implications for Agentic AI
Perhaps the most significant long-term implication of Space’s technology is its synergy with the rise of AI agents. Humans are relatively patient, but AI agents are not. In an hour of work, a human might interact with a handful of files. An autonomous AI agent, however, may execute thousands of granular read-write operations across a sprawling repository of data in that same window.
If every one of those operations requires a cloud-to-local transfer, the latency compounds, creating a significant performance ceiling for AI. Because Space FS is POSIX-compliant, it requires no bespoke APIs or complex integrations. An AI agent can point to the mounted Space volume and interact with it as it would a local disk, traversing directories and fetching only the required data at machine speed. This enables a level of AI throughput that was previously restricted by network and storage architecture.
The Vision: The "Infinite Computer"
The ultimate ambition of the team at Space is the realization of the "Infinite Computer." In this vision, the physical hardware on a user’s desk—the RAM, the CPU, and the local SSD—becomes secondary. Instead, the local machine functions as a portal into a vast, virtually unlimited pool of compute and storage resources.
By detaching the user experience from the constraints of local storage capacity, Space aims to democratize access to massive datasets. An architect with a thin-client laptop could interact with a city-scale 3D model as easily as a local text document. A data scientist could run queries across a multi-terabyte dataset without worrying about local disk space or bandwidth-heavy downloads.
Conclusion: A New Paradigm of Interaction
While industry announcements often suffer from an inflation of hyperbole, Space stands out for addressing a genuine, measurable friction in modern computing. The move from "storage" to "on-demand access" marks a significant evolution in how we interact with digital assets.
If the team can successfully scale their technology to meet the demands of enterprise-level object storage while maintaining the 20-millisecond latency threshold, they may well achieve their goal of making the cloud feel as local as a hard drive. For the average user, this means the end of "syncing" and the beginning of a seamless, truly borderless digital workspace. For the industry at large, it provides the infrastructure necessary for the next generation of AI agents to operate at their full, unthrottled potential.
As we look toward a future where our digital "stuff" is increasingly untethered from our physical hardware, companies like Space are providing the bridge to that reality—ensuring that no matter how much data we accumulate, it remains instantly accessible, right where we need it to be.